How much silence each ElevenLabs voice model leaves
We measured the same sentence with three voices and three ElevenLabs models. A table of internal silence in seconds for each combination, so you can choose with a number.
Also in: Español
Picking a synthetic voice is usually done by ear. The silence each model puts between phrases, on the other hand, can be measured.
If you use the voice in a video, that silence matters: every extra pause makes the piece longer and takes rhythm out of it. So we measured one sentence, with three natural breaks, on three voices and three ElevenLabs models (spoken in Spanish).
The table
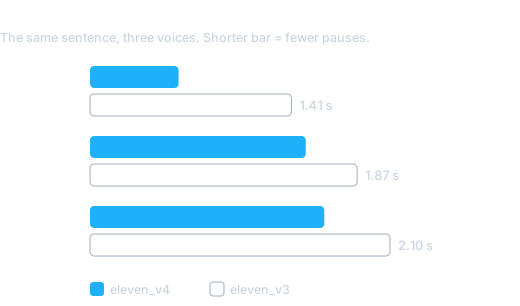
Seconds of internal silence in the same sentence. Less means fewer gaps.
| Voice | eleven_v4 | eleven_v3 |
|---|---|---|
| Sarah | 0.62 s | 1.41 s |
| Matilda | 1.51 s | 1.87 s |
| Chris | 1.64 s | 2.10 s |
eleven_v4 leaves less silence than eleven_v3 on all three voices. The biggest
gap is Sarah's: from 1.41 to 0.62 s.
The third model, multilingual_v2, was the worst on Sarah: it put 7 pauses
inside the same sentence.
What happens in a whole piece
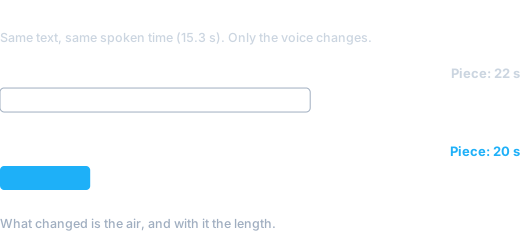
One sentence is a small sample. We built a two-scene piece with the same spoken time, 15.3 s, and changed only the voice:
| OpenAI voice (ash) | Sarah with eleven_v4 | |
|---|---|---|
| Total air | 2.82 s | 0.82 s |
| Piece length | 22 s | 20 s |
Same text and same spoken time: what changed was the air, and with it the length.
How to use this number
- Measure with your own sentence. One with several natural breaks shows the differences between models best.
- Compare internal silence, not just how good it "sounds".
- If the video is public, check the license: ElevenLabs commercial use needs a paid plan.
One caveat: this is our own measurement, on one sentence and one piece. It helps you choose with a number in hand; it is not a general benchmark of the voices.
Have a case where you want to see this working? Tell us what your business does and we will build it on your own material.